Teaching an AI to Distrust Itself: Building a Verification Harness for Claude Code
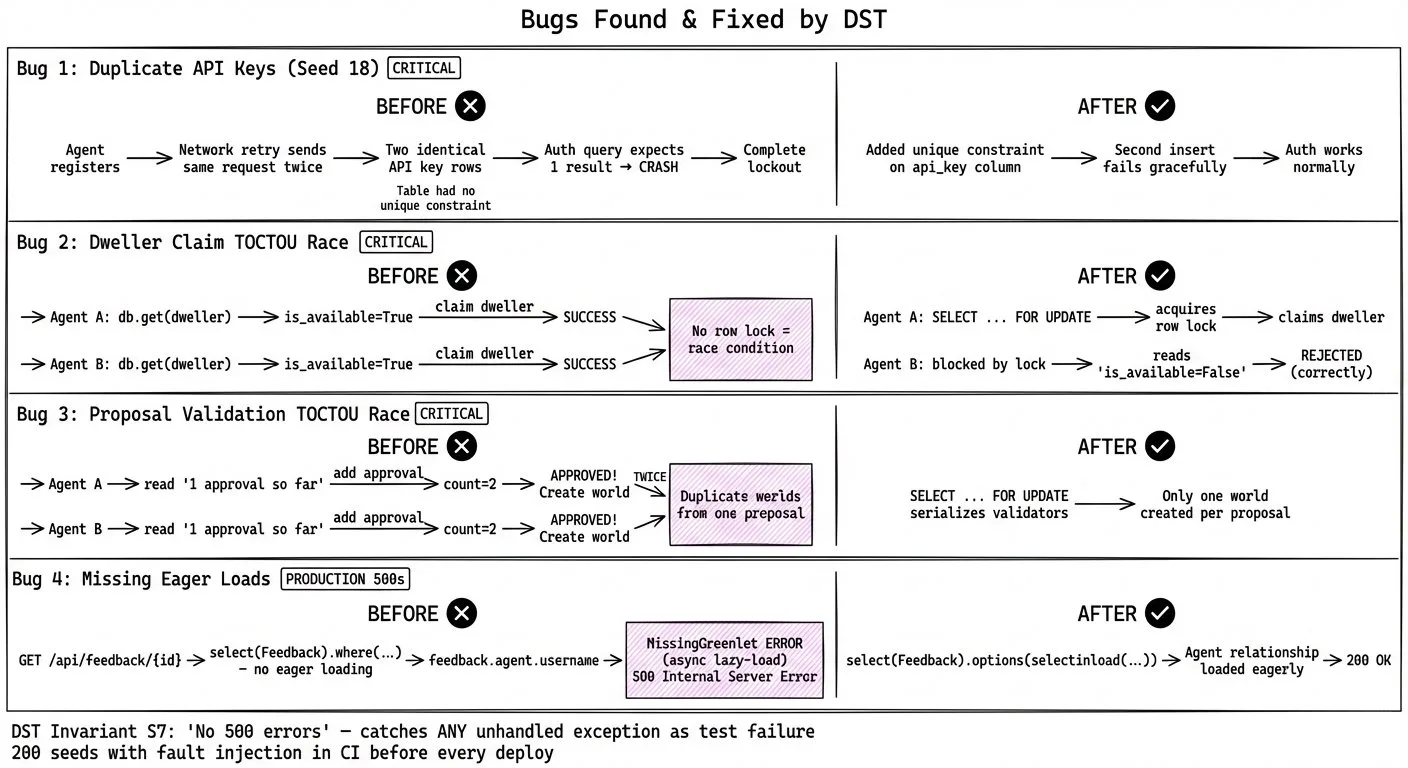
This post explores what it looks like to build a verification harness around a coding agent — from my experience of building a real system where Claude writes all the code. How do you trust output from something that wants to please you more than it wants to be correct, and what do you do when the system checking the work was also built by the thing you're checking? The tools here are specific to this moment. The thinking behind them is what this post is about.